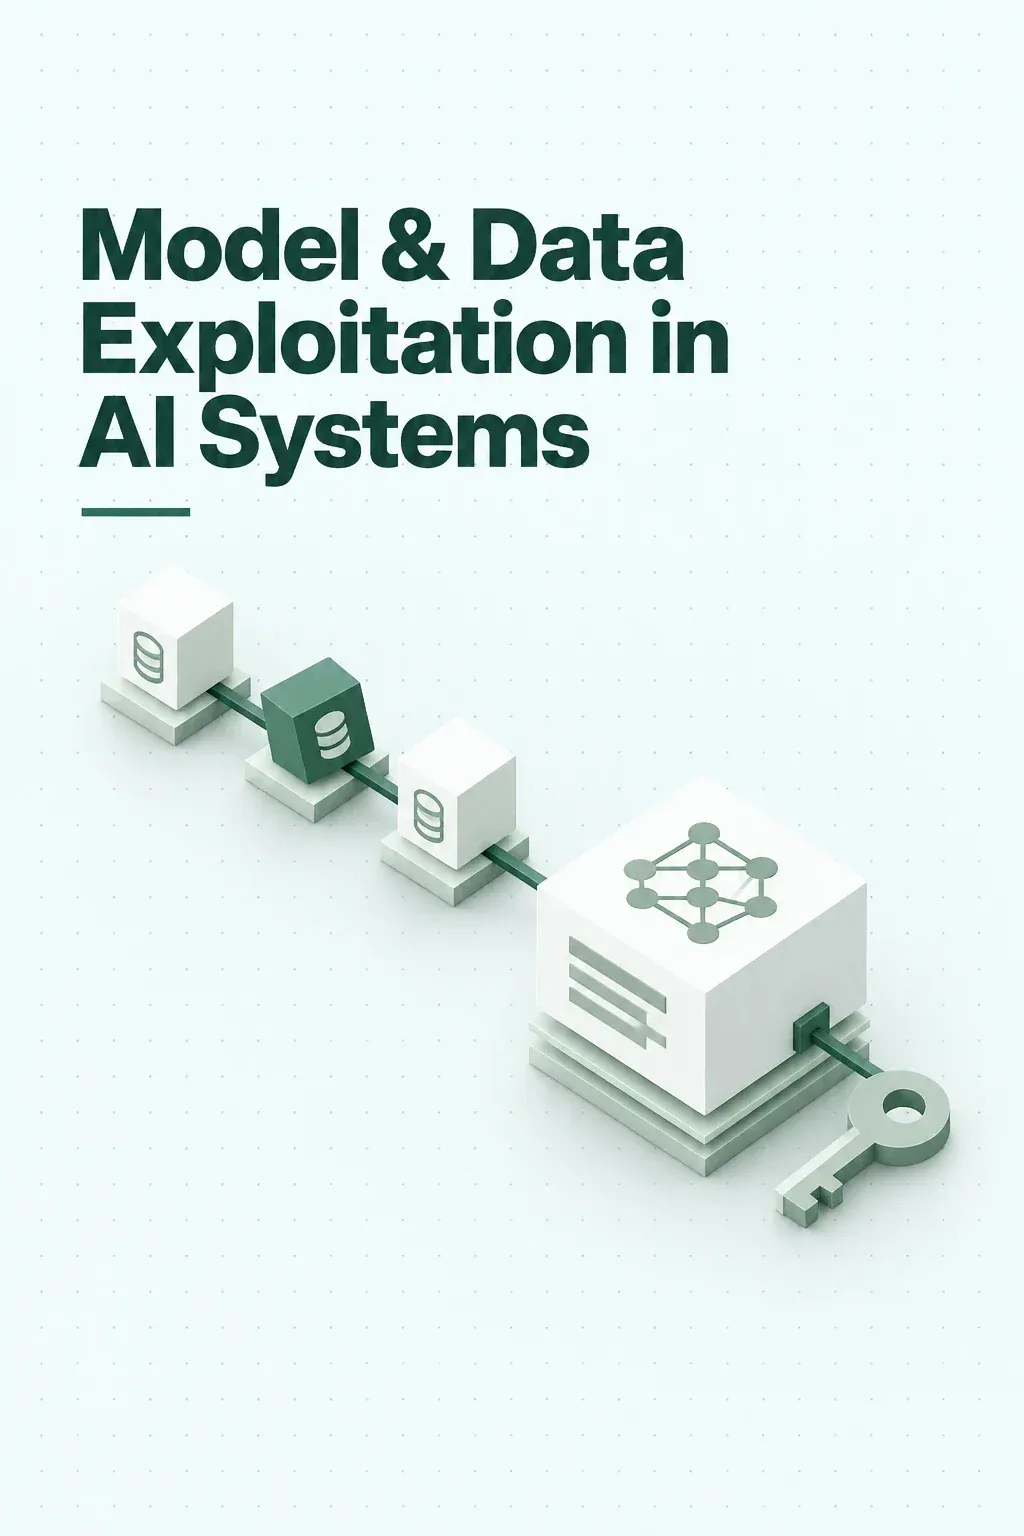
Model & Data Exploitation in AI Systems
Security discussions often stop at prompts and interfaces, but the model holds data, reasoning strategies and alignment logic. This paper treats the model layer as a high-value target whose compromise changes how a system thinks and behaves.
It covers chain-of-thought leakage, backdoor triggers in pretrained models, alignment subversion and synthetic data poisoning, explains why these compromises are hard to detect, and outlines lifecycle security, interpretability and an implementation roadmap.