
SRE Consulting That Starts with What Users Experience
Reliability work goes wrong when it measures servers instead of customers. Our SRE consulting starts with the journeys that matter to users and the business, and turns them into service level objectives your team can track.
User journeys
Sign-in, checkout, payments, or the actions customers cannot do without.
Current behavior
Availability, latency, and error rates measured today.
Business impact
What an hour of downtime or slow service costs.
Service level objectives the business agreed to
Observability Consulting: See Problems Before Customers Do
Our observability consulting connects logs, metrics, and traces to the objectives, so the team sees what changed, where, and why, instead of a wall of dashboards nobody reads.
Telemetry
Telemetry
Logs, metrics, and traces collected consistently across services.
Signals
Signals
Measures tied to the objectives, with noise filtered out.
Actionable alerts
Actionable alerts
Alerts routed to the owner with the context to act.
The owner knows, with context, before the customer does
Request a free SRE consultation
Site Reliability Engineering Consulting, Step by Step
We introduce site reliability engineering in steps your team can absorb. Cognativ has applied this work to a telecom provider whose outages and performance failures fell 80% and a fintech platform that reached 99.99% availability.
-
Define
Agree on objectives and error budgets for critical journeys.
-
Observe
Instrument services and build alerts tied to the objectives.
-
Respond
Set on-call, runbooks, and incident roles.
-
Learn
Run blameless reviews and fix causes in the system.
Reliability for Teams Without a Dedicated SRE Function
Most mid-sized companies do not have, and do not need, a separate SRE team. We build the practices into the teams that already build and run the services: shared objectives, an on-call rotation people can sustain, and reviews that turn incidents into fixes.
Your engineers learn the practices on their own services, so reliability keeps improving after the engagement ends.
SRE and Observability Consulting Questions
What to expect before you start.
What does an SRE consultant do?
An SRE consultant helps a team keep services reliable: setting service level objectives with the business, building monitoring and alerting around them, and introducing incident response and review practices.
What is the difference between monitoring and observability?
Monitoring tells you that something is wrong. Observability gives the team enough data from logs, metrics, and traces to understand why, including problems nobody predicted.
Which observability tools do you work with?
The approach is tool-neutral: it applies to Datadog, Grafana and Prometheus, New Relic, Azure Monitor, Amazon CloudWatch, and similar platforms, starting with what you already run.
Do we need a dedicated SRE team?
Not necessarily. Many companies adopt SRE practices inside existing development or operations teams; we recommend a structure that fits your size.
How is SRE consulting different from DevOps consulting?
DevOps consulting improves how changes reach production. SRE consulting focuses on how services behave once they are there and how the team responds when they fail.
How does an engagement start?
With a free first consultation about the services that matter most and recent incidents, then a reliability review with a fixed scope and fee.
Reliability Case Studies
Platforms where outages, incident response, and monitoring changed how reliably customers were served.

Virtual CTO Cuts Telecom Outages and Failures 80%
Software Reliability
Platform Modernization
Release Management
Virtual CTO
Virtual CTO Cuts Telecom Outages and Failures 80%
Cognativ provided Virtual CTO leadership to stabilize a telecom environment affected by outages, performance failures, and reactive technical operations.
The work reduced outages and performance failures by 80%, improved delivery discipline, and gave the business a more reliable operating foundation.
Review the Outage Reduction
Fintech Platform Reaches 99.99% Availability
Platform Modernization
Elastic Scaling
Observability
Virtual CTO
Fintech Platform Reaches 99.99% Availability
Cognativ stepped in with Virtual CTO leadership to stabilize a fintech platform affected by reliability, performance, and scalability pressure.
The engagement helped the client reach 99.99% availability, restore customer confidence, and create a stronger foundation for regulated growth.
See the Fintech Stability Case
Telecom Rebuild Restores Customer Trust
Platform Modernization
Telecom Software
Incident Management
Fault Tolerance
Telecom Rebuild Restores Customer Trust
Cognativ helped a regional telecommunications company rebuild its OSS/BSS platform and realign delivery to restore customer trust and protect key accounts.
The case reports customer satisfaction rising from 0% to 95% and full key-account retention within 12 months.
Explore the Telecom Transformation
Ecommerce Order Cancellations Fall 22%
Systems Integration
Workflow Automation
Order Management
Observability
Ecommerce Order Cancellations Fall 22%
Cognativ implemented integration automation and real-time observability to reduce failed orders, improve customer communication, and stabilize fulfillment operations.
The work reduced order cancellations by 22% and manual order triage by 40%; more proactive support contributed to an 18-point rise in Net Promoter Score.
See the Order RecoveryRelated Software Development Insights
Recent Cognativ articles on building, running, and modernizing business software.
Functional Testing: Types, Tools, Strategies and Best Practices
Unit, integration, regression and acceptance tests plus Selenium, Playwright and Appium: how to design a functional testing suite you can trust on each release.
Best Programming Languages to Learn in 2026: Top Picks by Use Case
Python, TypeScript, SQL, Rust and more: see which languages lead the 2026 rankings, what each is best for and how AI coding agents shift what to learn next.
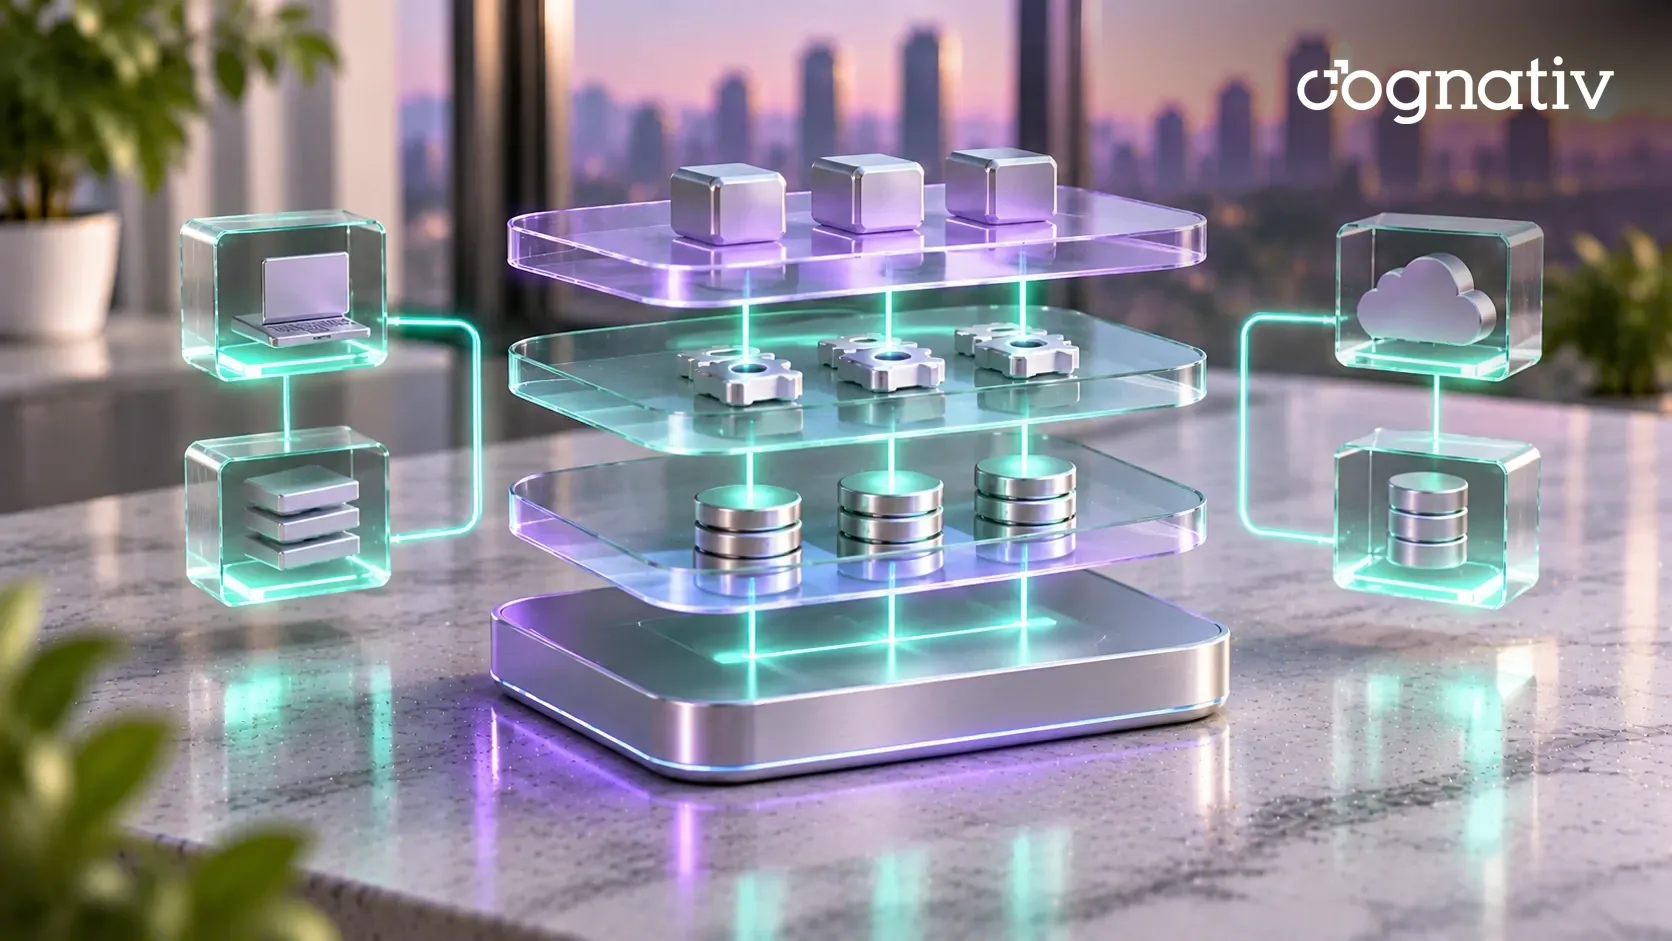
Application Architecture: Key Concepts, Types and Patterns
From monoliths and N-tier layers to microservices, events and serverless: how each architecture pattern works, its trade-offs and a framework for choosing.